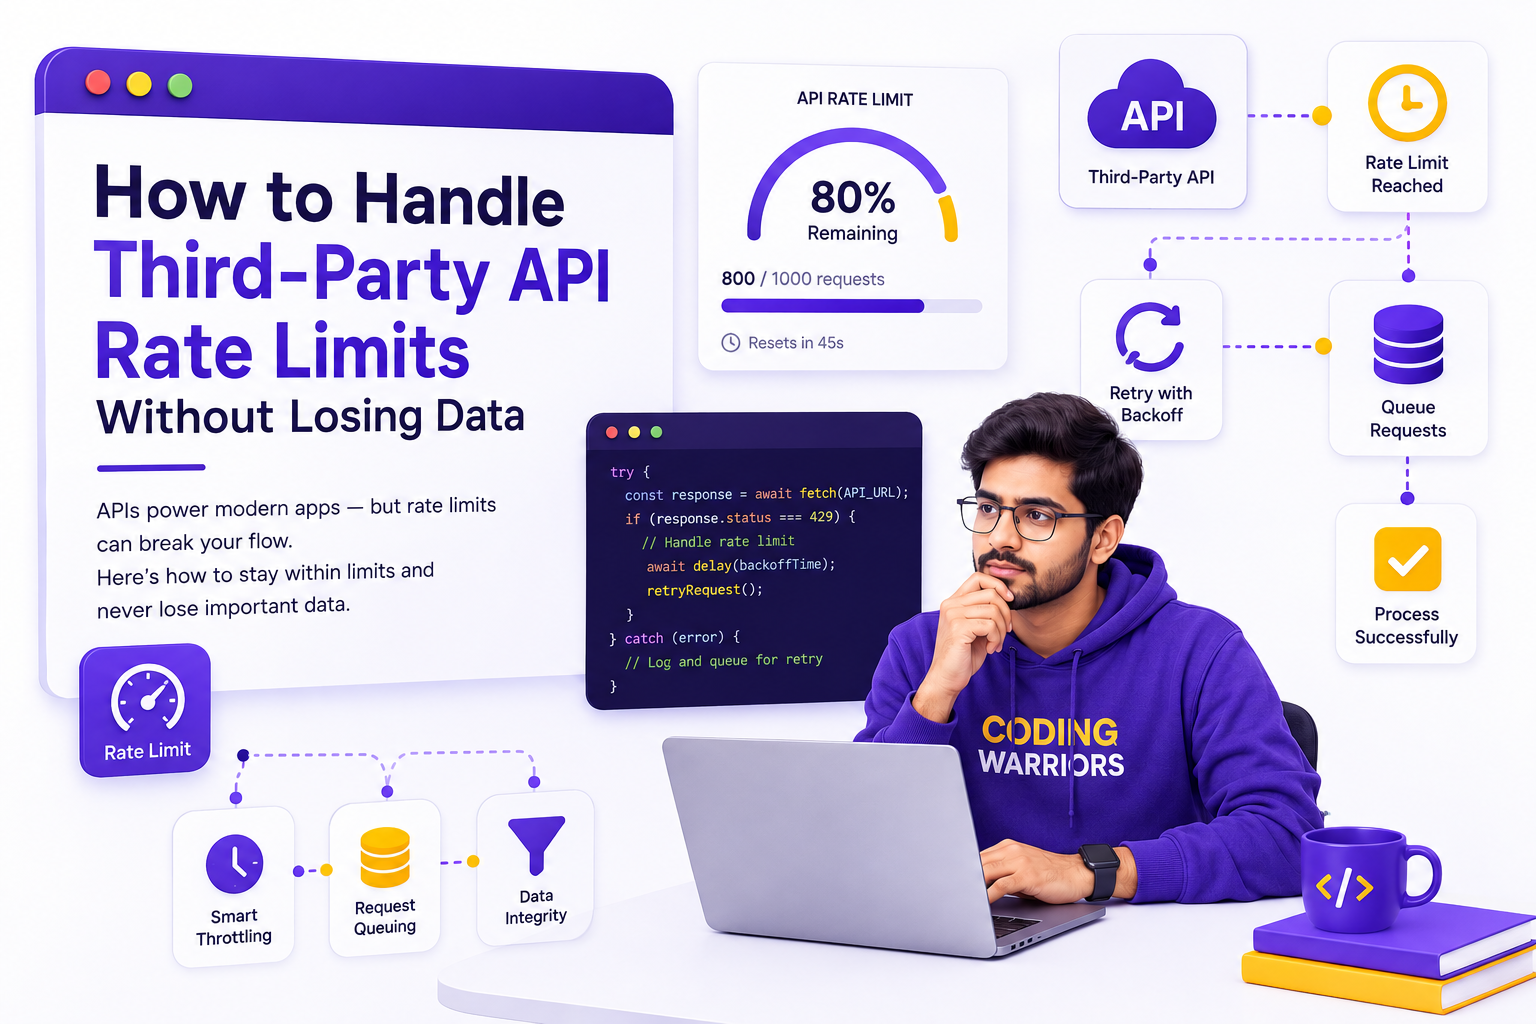
Every third-party API has limits, and eventually your integration will hit them. The difference between a well-built integration and a fragile one is what happens next.
The naive approach fails quietly
A basic integration fires a request, gets a 429 rate-limit response, and either crashes or silently drops the data. Nobody notices until a customer complains that their order never synced, days later.
Queue instead of fire-and-forget
Instead of sending requests directly and hoping they succeed, route API calls through a queue. If a request fails due to rate limiting, it goes back into the queue with a delay instead of being lost. This alone prevents the majority of silent data loss.
Respect the Retry-After header
Most APIs that rate-limit you will tell you exactly how long to wait before retrying, usually in a Retry-After header. Reading and respecting this header, rather than guessing with a fixed delay, means you recover faster and avoid getting rate-limited again immediately.
Exponential backoff for the rest
When an API doesn't tell you how long to wait, exponential backoff — waiting progressively longer between retries — prevents you from hammering a struggling service and making things worse.
Alert before it becomes a pattern
One rate-limit hit is normal. Repeated rate-limit hits over an hour is a sign your integration needs a redesign — either batching requests more efficiently or negotiating a higher limit with the provider. Monitoring should flag this trend, not just individual failures.
Rate limits aren't a bug in the third-party API — they're a constraint you design around, the same way you'd design around any other system limit.
R
Rohan Mehta
Written at Coding Warriors